Introducing Boreal-H3: The Next Frontier in Video Is Post-Training

Written by
Creatify Research Team
•
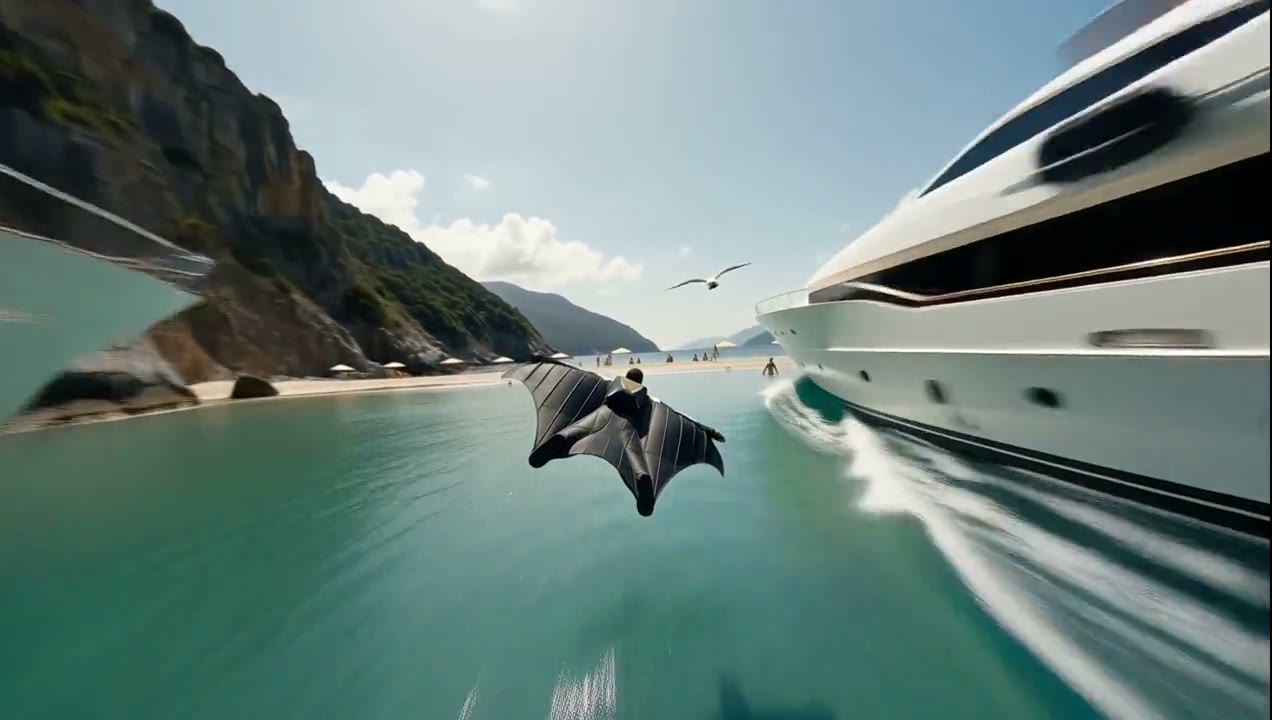
Boreal-H3 is the new top of the Boreal family. Where Boreal made advertising video cheap enough to generate at scale, Boreal-H3 raises the quality ceiling for the shots that carry a campaign: the product must keep its exact label, the creator must stay the same person, the camera must go where the brief says, and the action must actually happen. It is built by post-training MiniMax H3 with the same Recursive Self-Improvement loop we used for Boreal, aimed squarely at advertising.
01 · Why post-train
Why post-train for advertising
We launched our Creative Agent in May with a simple premise: video creation should begin with a prompt. The agent develops concepts, generates shots, and assembles videos. Customers loved the simplicity. Their biggest complaint was cost. Every shot explored requires another generation, and frontier list prices forced teams to ration attempts. The LLM workflow—generate a hundred variations and keep the best—was simply too expensive for video.
Advertising puts unusually specific demands on video generation: product fidelity, natural creator performances, and faithful execution of the brief. A skincare bottle needs to keep its shape and label as it moves through a creator’s hands. A product demonstration needs to show the requested result. A spoken hook needs to sound natural while preserving the script, and camera movements need to follow direction without breaking continuity. These are the capabilities we target with post-training.
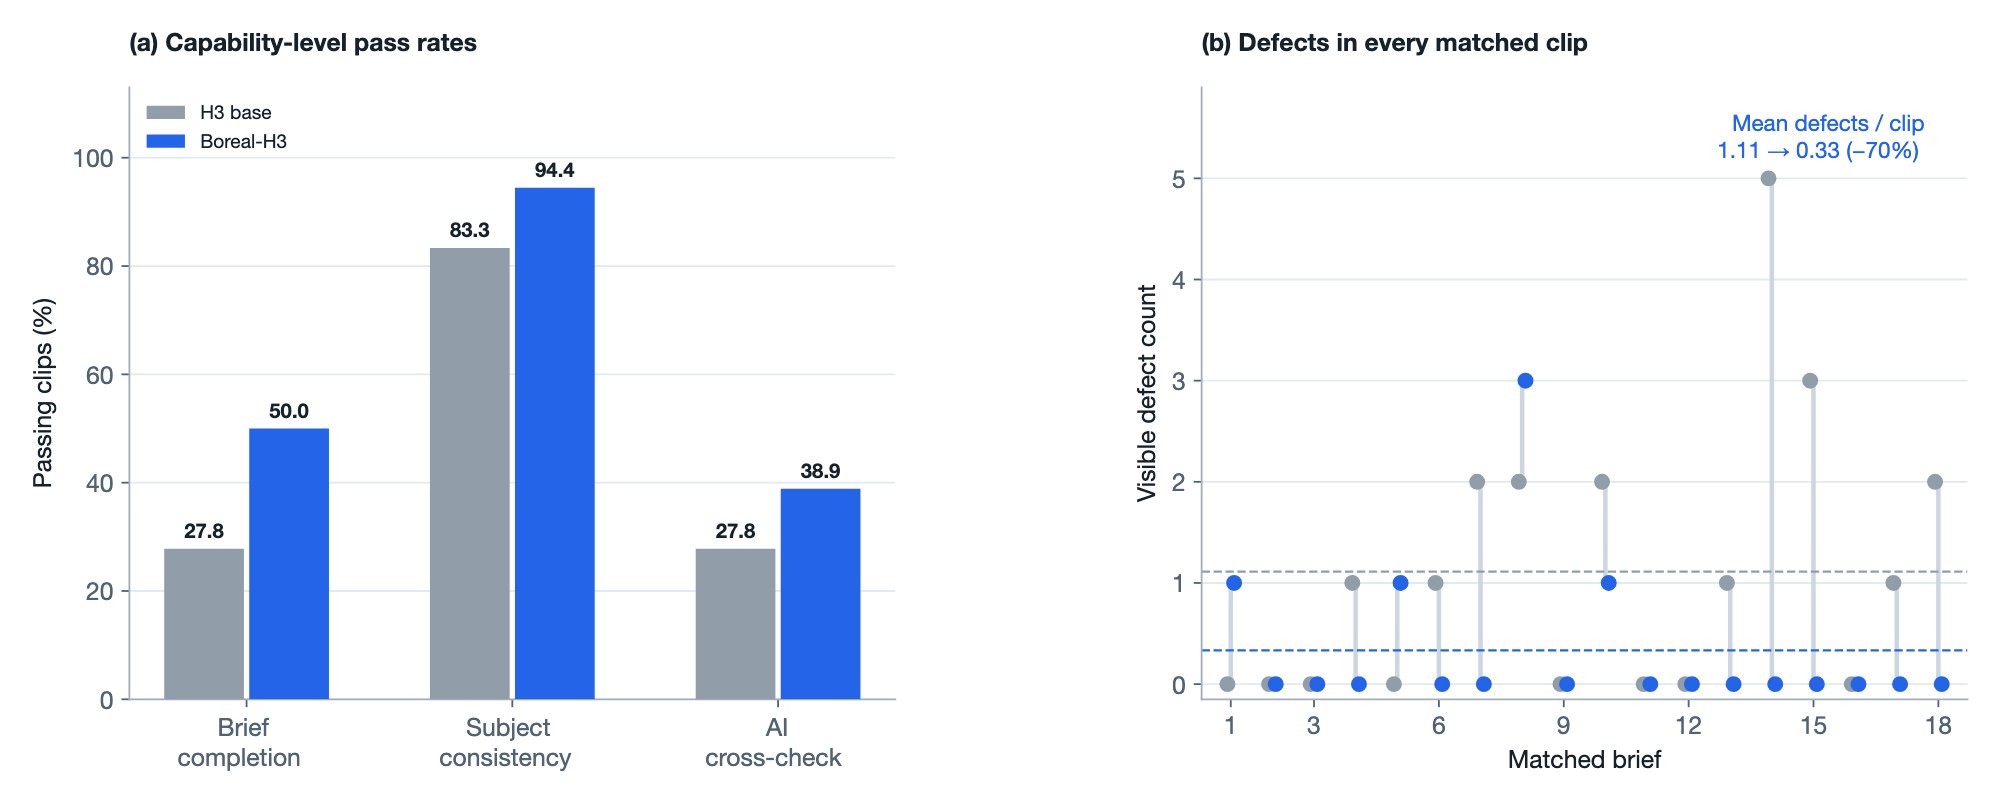
These requirements make advertising a proving ground for our feedback-driven post-training paradigm. Human preferences and customer acceptance reveal where the model falls short, guiding what data to collect, which training interventions to pursue, and what to improve next. For Boreal-H3, building on MiniMax H3 shifted our focus toward reference fidelity, identity, and brief execution. In controlled evaluations, brief success rose from 28% to 50% and identity match from 83% to 94%. This is our path towards recursive self-improvement: better video models, and a better process for producing the next one.
02 · Post-training architecture
Post-training architecture: learning what to improve next
Our post-training goes beyond a one-off SFT or LoRA fine-tuning run. Instead, we build a closed-loop system that decides what to improve next—across data, training, and inference. We designed it this way because different advertising failures require different interventions, and a higher overall score can hide regressions in product fidelity, identity, or brief execution. With human-calibrated evaluation at the core, each round diagnoses the failure, tests a targeted change, and carries the result forward—improving both the model and the process that produces its successor.
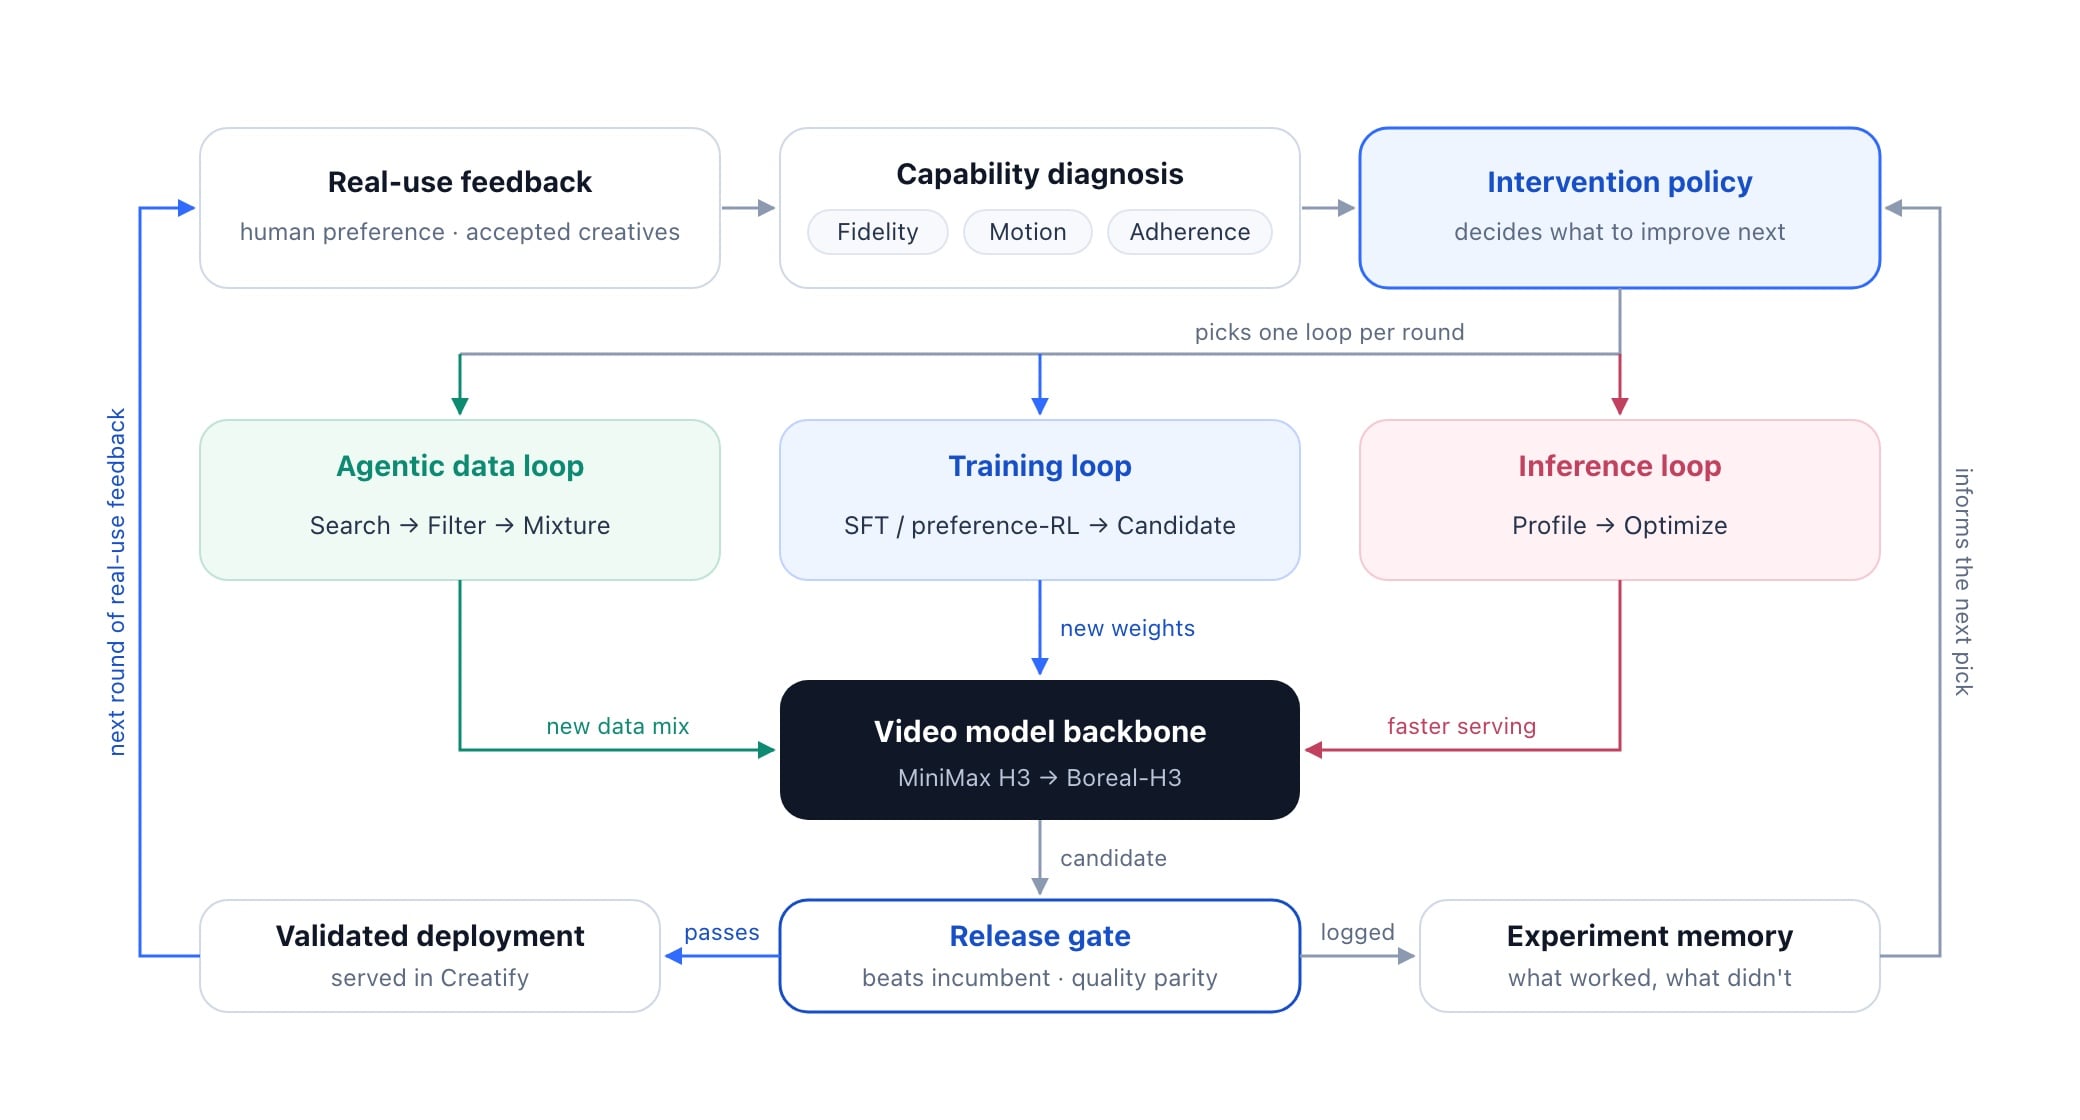
A better-looking clip is not necessarily a better ad. We assess capabilities separately, combining task-specific metrics, human review, and automated judges checked against human choices.
When feedback is unreliable, revise the evaluator or reward before optimizing the generator. A misleading signal calls for better measurement, not more training. [1]
Missing coverage calls for targeted collection; paired demonstrations can support supervised fine-tuning; open-ended preferences can support reinforcement learning, including H3’s GRPO adaptation. [2] Serving bottlenecks call for runtime optimization with quality checks. SFT and RL are tools within the loop—not a fixed recipe. [3]
We compare candidates with the current model on fixed capability tests, not training loss alone. Blind A/B comparisons run in both viewing orders; ties and order disagreements remain ties. Promising candidates require confirmation before promotion. Every verdict and reason enters shared memory, informing the next data request, training recipe, or serving experiment.
The goal is not a single fine-tuned checkpoint, but a process that learns what to improve next.
Agents automate collection and routine proposals; researchers define objectives, revise evaluators, and approve releases.
References
Lian et al. (2025). SoliReward: Mitigating Susceptibility to Reward Hacking and Annotation Noise in Video Generation Reward Models. Related work on unreliable video reward signals; not a claim that Boreal uses the SoliReward architecture.
Liu et al. (2025). Flow-GRPO: Training Flow Matching Models via Online RL. Related work on online RL for flow-matching generators.
Xue et al. (2026). A Systematic Post-Train Framework for Video Generation. Describes a staged SFT, RLHF, prompt-enhancement, and inference-optimization framework. Boreal focuses on the feedback-driven choice of interventions across rounds.
03 · Evaluation results
Evaluation results
We evaluate Boreal-H3 on real-world advertising briefs using blinded human review, structured AI assessment and general video-quality metrics. Across six frontier models, Boreal-H3 achieves the highest observed Ads quality pass rate (35.3%), with competitive perceptual quality. Post-training improves brief completion and reduces visible defects.
3.1 · Metrics and evaluation methods
Human studies use anonymized outputs and randomized placement. AI assessment scores execution against the original brief and reference; perceptual metrics provide an independent quality check.
Matched 720p / 768p outputs. Blinded human studies and frontier AI scoring are separate evaluation streams.
Evaluation protocol
Frontier comparisons use matched image-to-video advertising briefs at 720p, or the nearest supported 768p. Structured AI evaluation assesses prompt following, reference consistency and visual realism against the original brief and reference, with the producing model’s identity withheld.
Blinded human studies use anonymized outputs and randomized placement. Human preference results and frontier AI scoring are reported as separate evaluation streams.
Post-training evaluation compares H3 base with the complete Boreal-H3 advertising workflow on matched production briefs. Training rewards are evaluated separately from benchmark performance.
3.2 · Comparison with frontier video models
Boreal-H3 leads the observed Ads quality ranking at a $0.04/s launch price—50% off H3 pricing. Figure 2 shows quality against price and latency; Table 1 ranks the tabulated models by Ads quality.
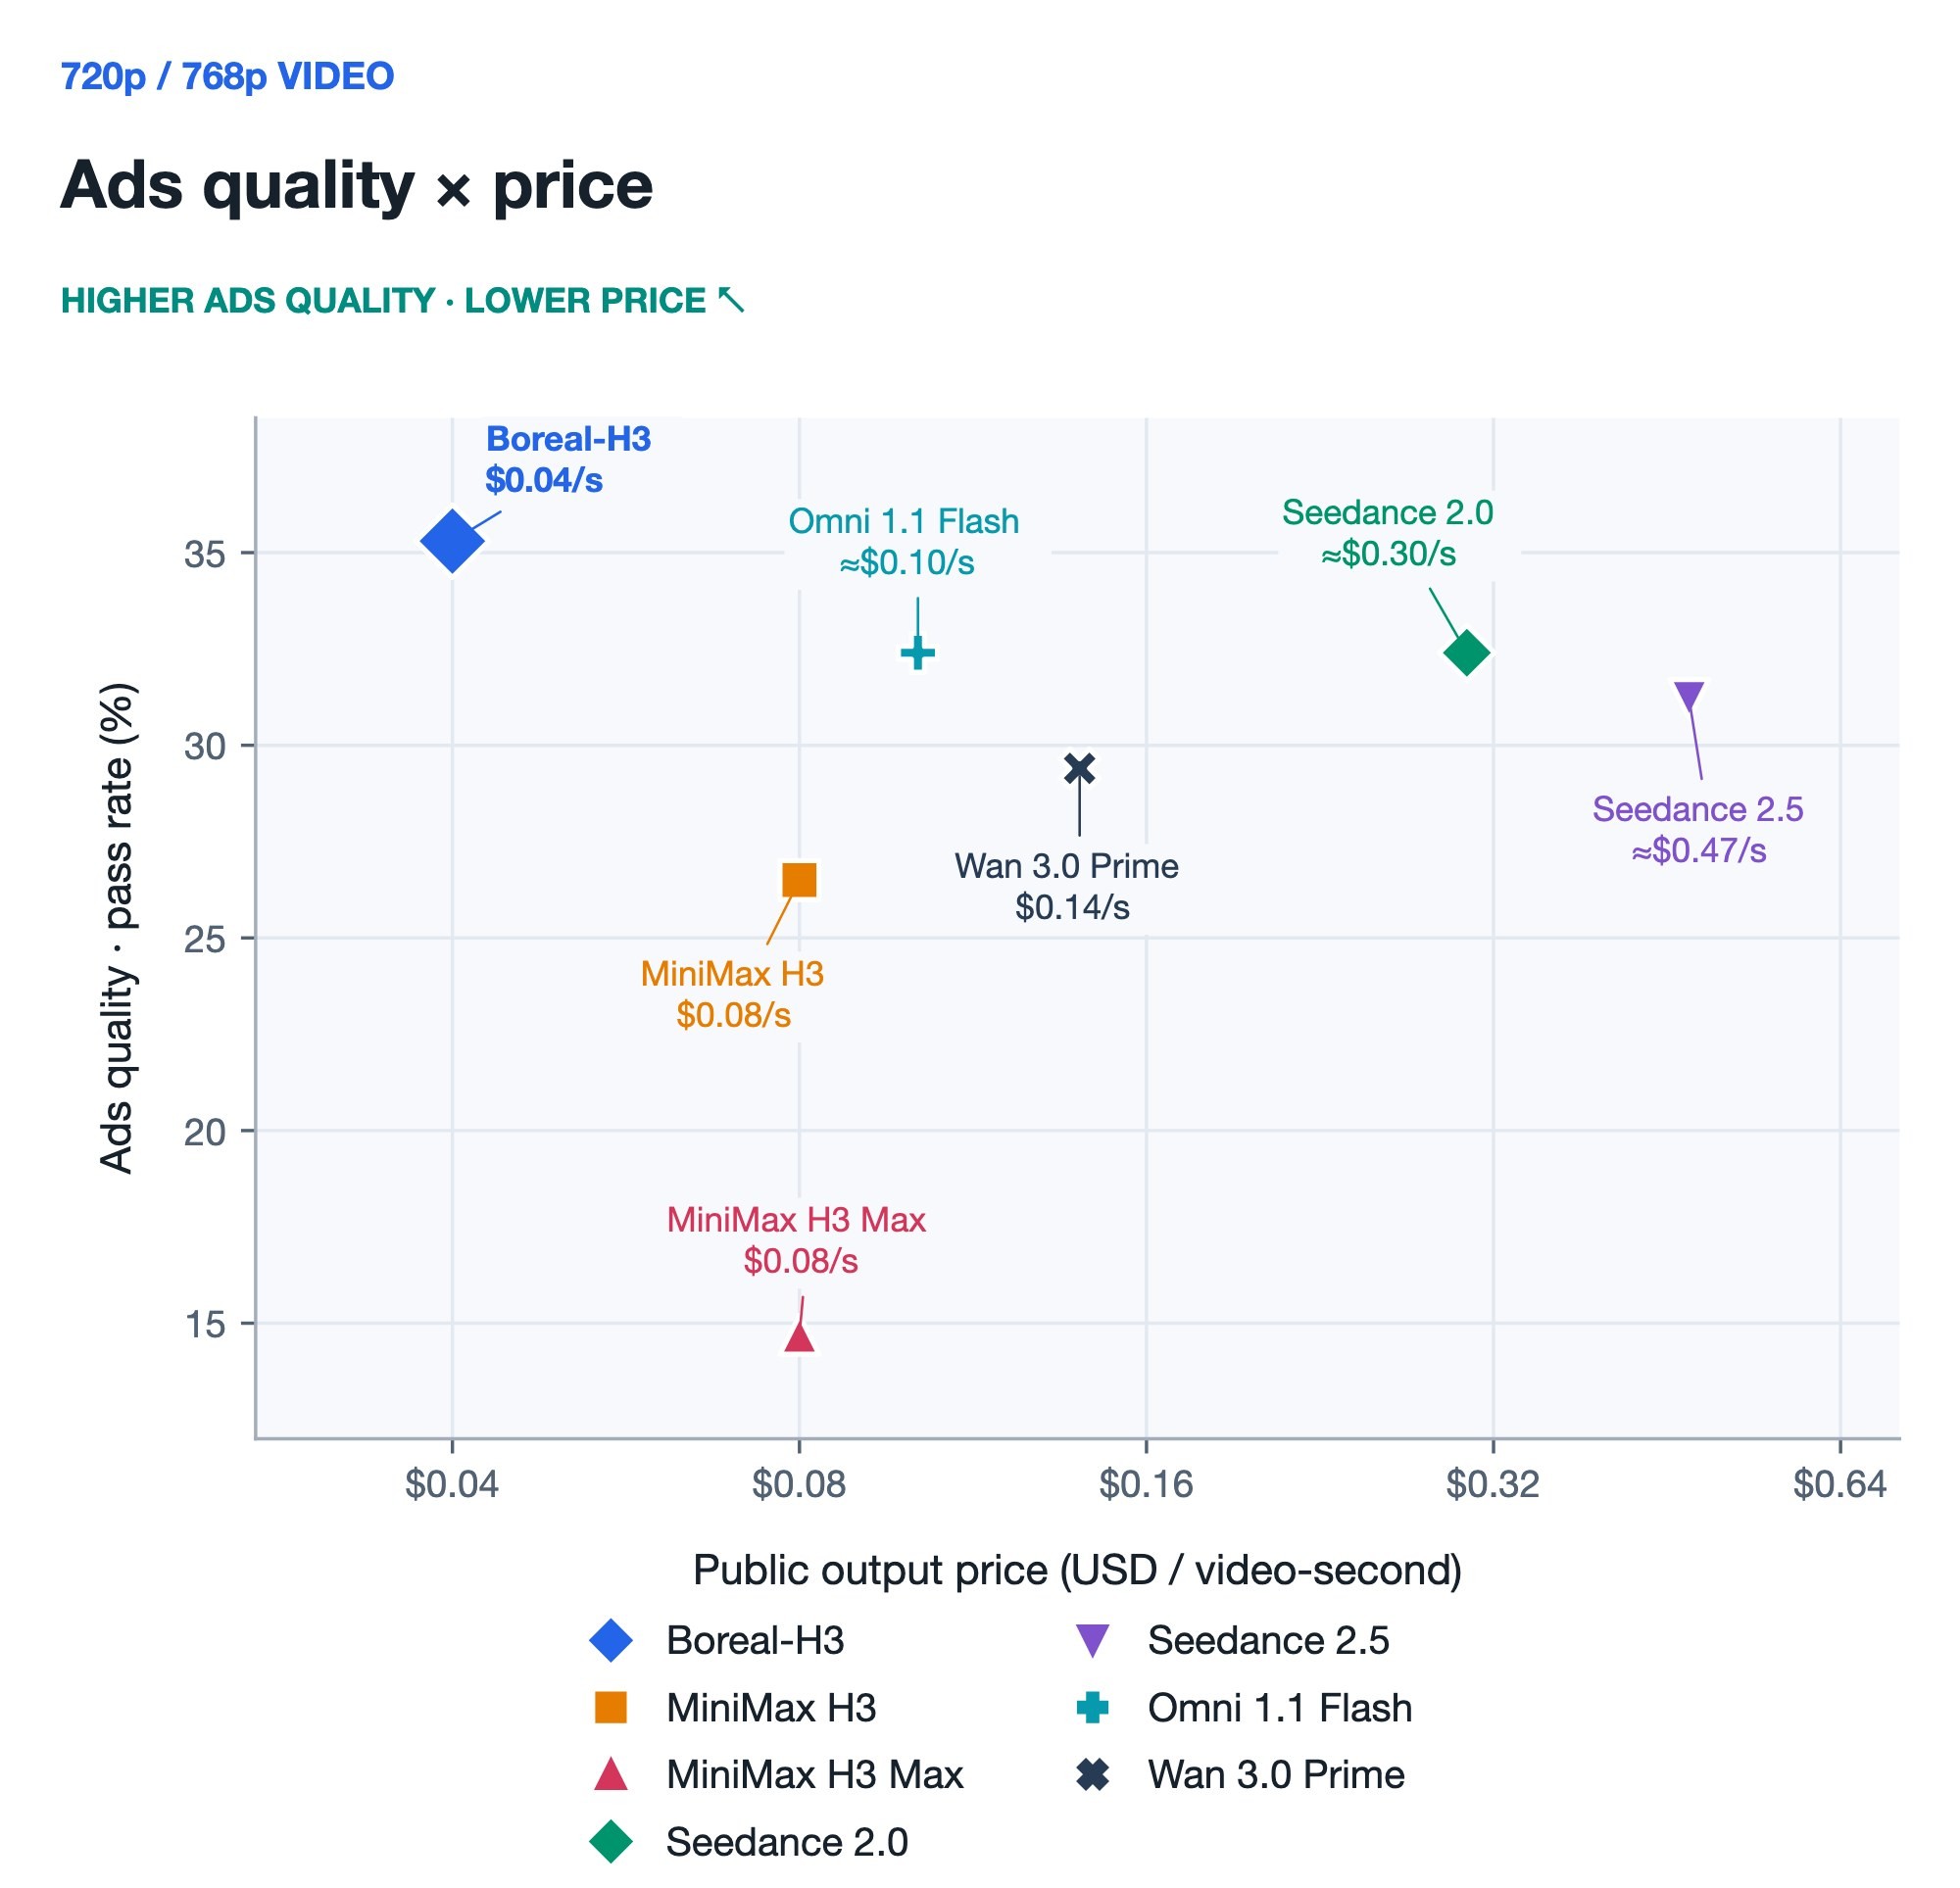
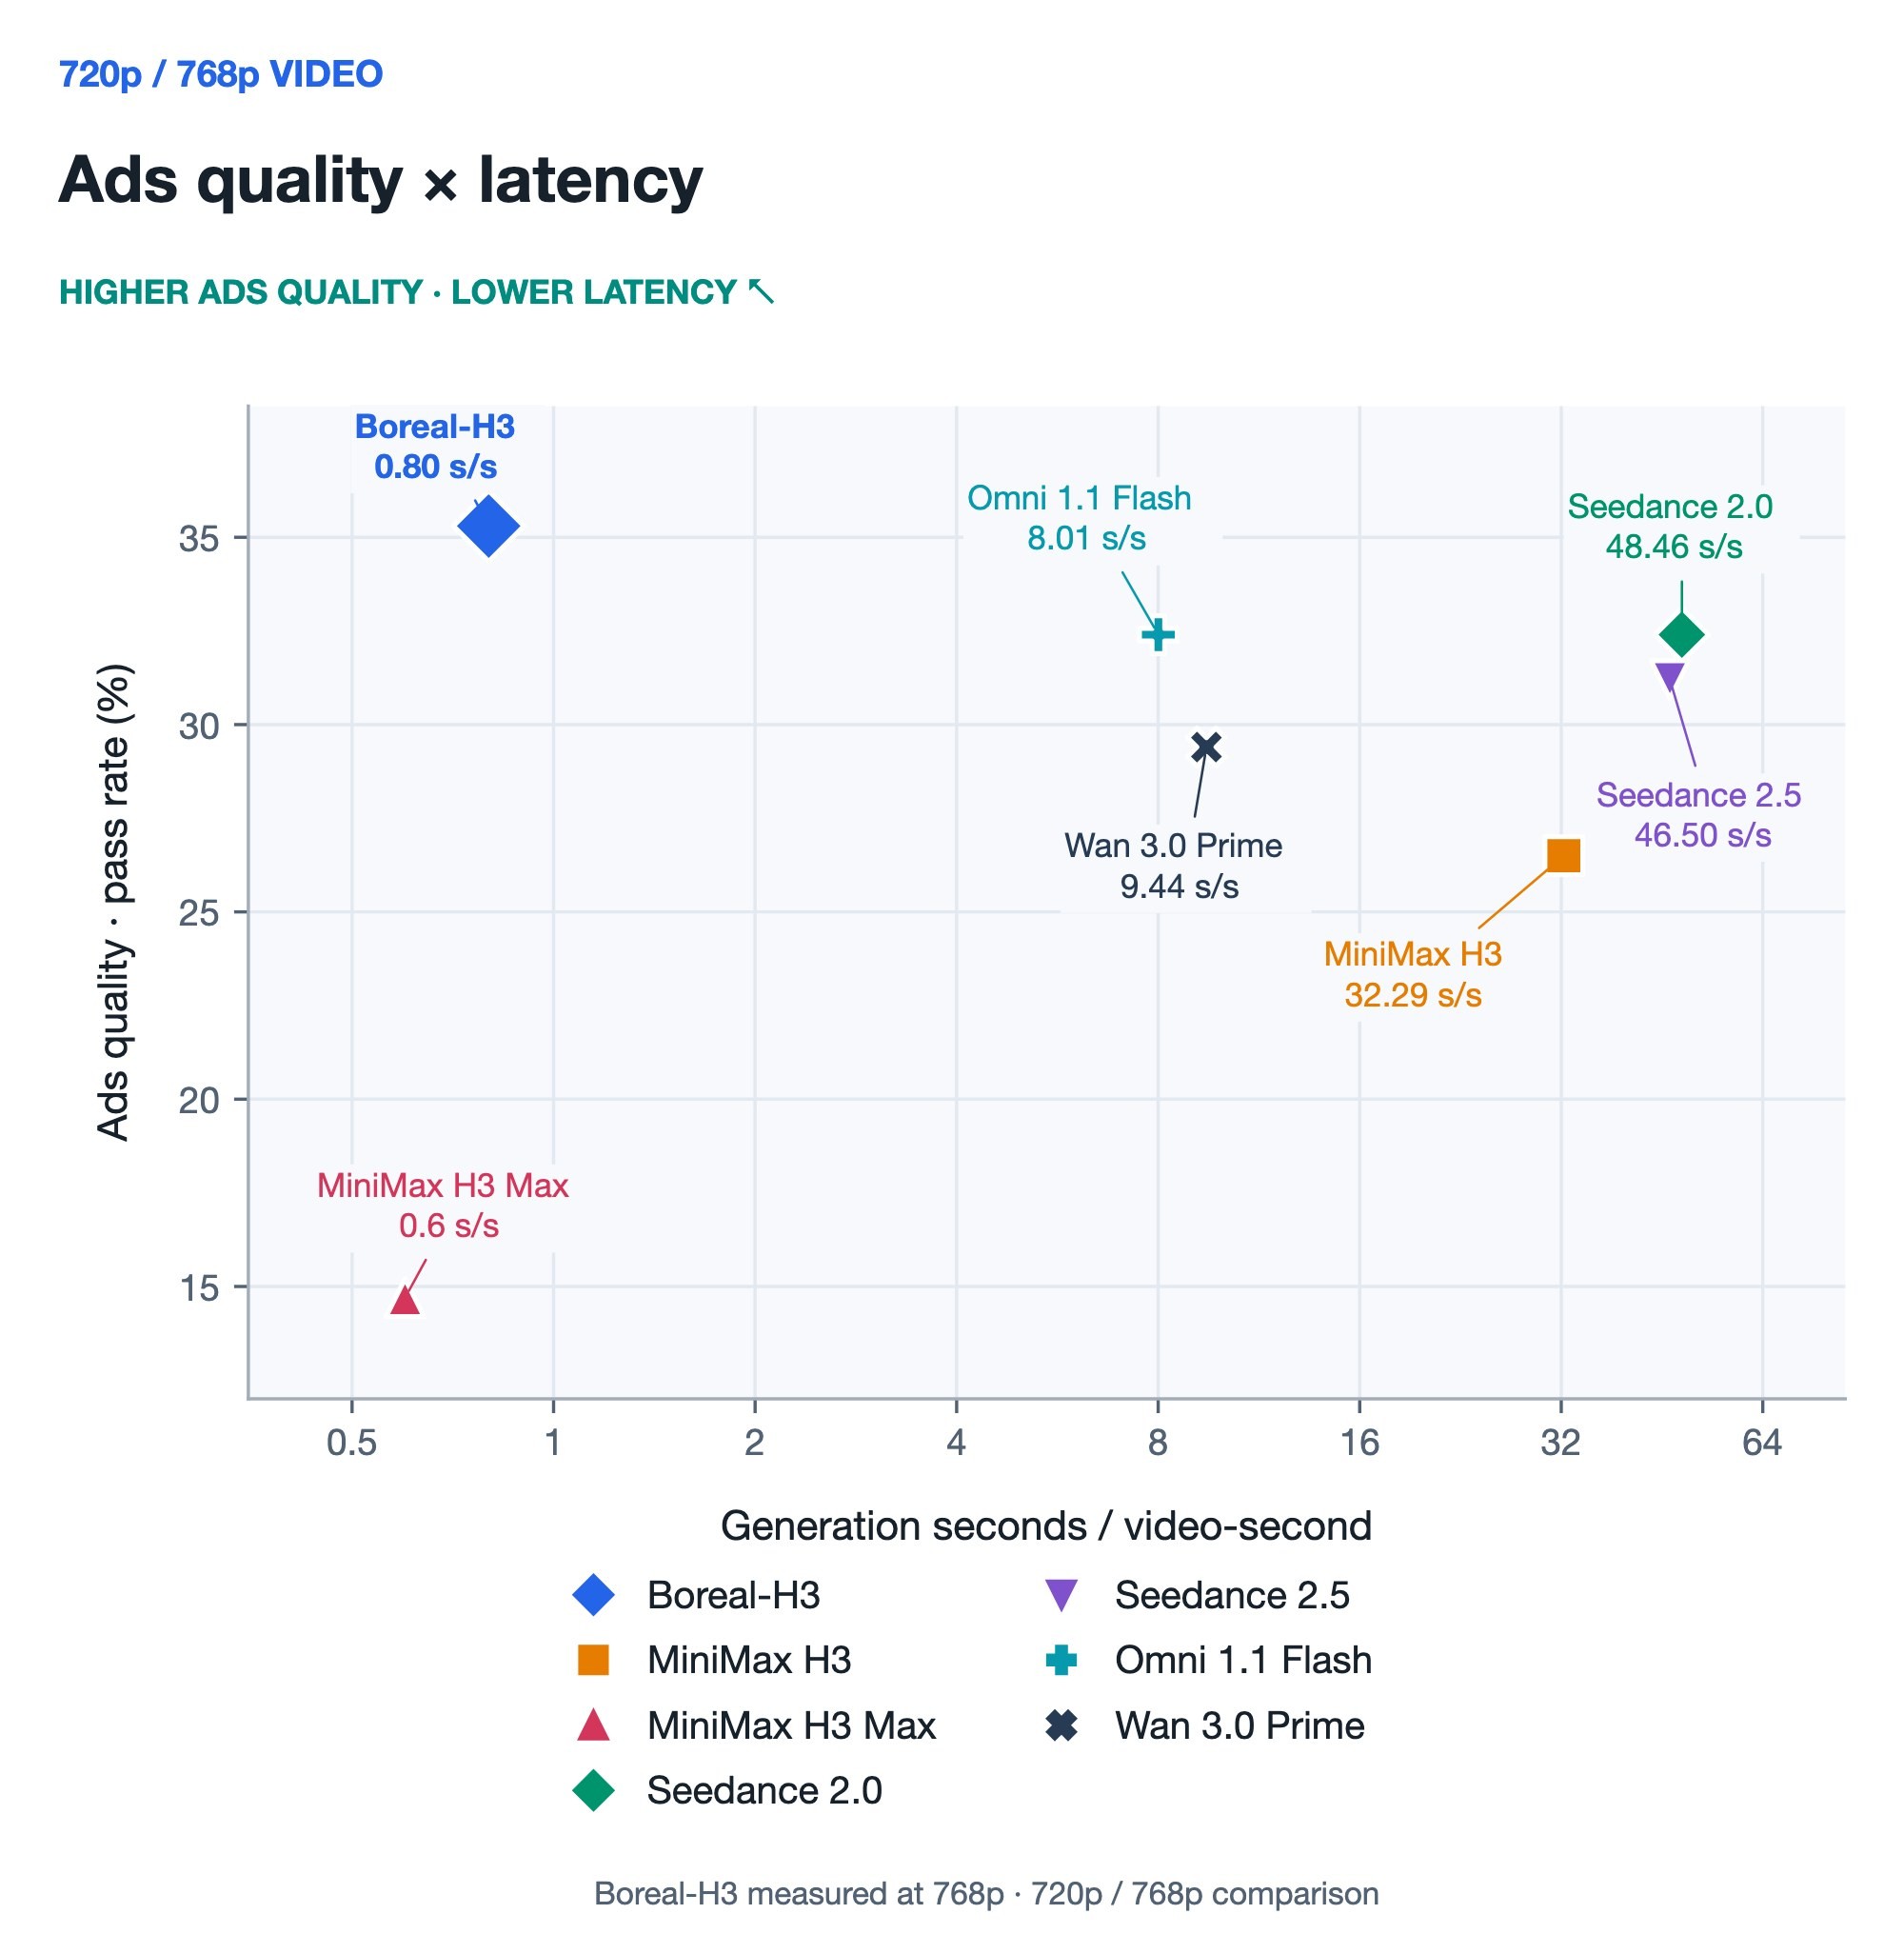
Table 1 · Boreal-H3 compared with frontier video models
Model | Ads quality (%) ↑ | Q-Align ↑ | MUSIQ ↑ | Motion ↑ | Latency (s/s) ↓ | Price ($/s) ↓ |
|---|---|---|---|---|---|---|
Boreal-H3 | 35.3 | 4.759 | 66.73 | 0.556 | 0.80 | 0.04 |
Omni 1.1 Flash | 32.4 | 4.736 | 65.84 | 0.512 | 8.01 | ≈0.10 |
Seedance 2.5 | 31.2 | 4.639 | 63.06 | 0.573 | 46.50 | ≈0.47 |
Wan 3.0 Prime | 29.4 | 4.792 | 69.06 | 0.406 | 9.44 | 0.14 |
MiniMax H3 | 26.5 | 4.771 | 66.61 | 0.504 | 32.29 | 0.08 |
MiniMax H3 Max | 14.7 | 4.675 | 64.30 | 0.545 | 0.6 | 0.08 |
Rows are ordered by Ads quality. Boreal-H3 latency is measured at 768p; comparator timings use API measurements and published provider reports.
Public pricing and latency sources
Public pricing checked September 30, 2026; 720p / 768p output rates. Boreal-H3’s $0.04/s launch offer is 50% off MiniMax H3’s $0.08/s 768p list price. Comparators use public list rates, excluding temporary promotions and input surcharges.
Seedance 2.0: published 720p rate $0.3034/s. Seedance 2.5: published approximate 720p rate $0.4730/s. Both are token billed; actual frame area changes the charge. Omni 1.1 Flash: $17.50 per million output video tokens × 5,792 tokens per 720p second, about $0.1014/s. Wan 3.0 Prime: $0.14/s at 720p (standard tier: $0.10/s). Extra input charges and promotions are excluded.
Boreal-H3: measured latency of 0.8 s/s at 768p. Comparator timings use recorded API measurements and official provider speed reports.
3.3 · Post-training versus H3 base
On difficult production briefs, completion rises from 27.8% to 50.0%, subject consistency from 83.3% to 94.4%, and visible defects fall 70% (1.11 → 0.33 per clip). Figure 3 measures the complete advertising workflow, combining prompt processing and post-training.
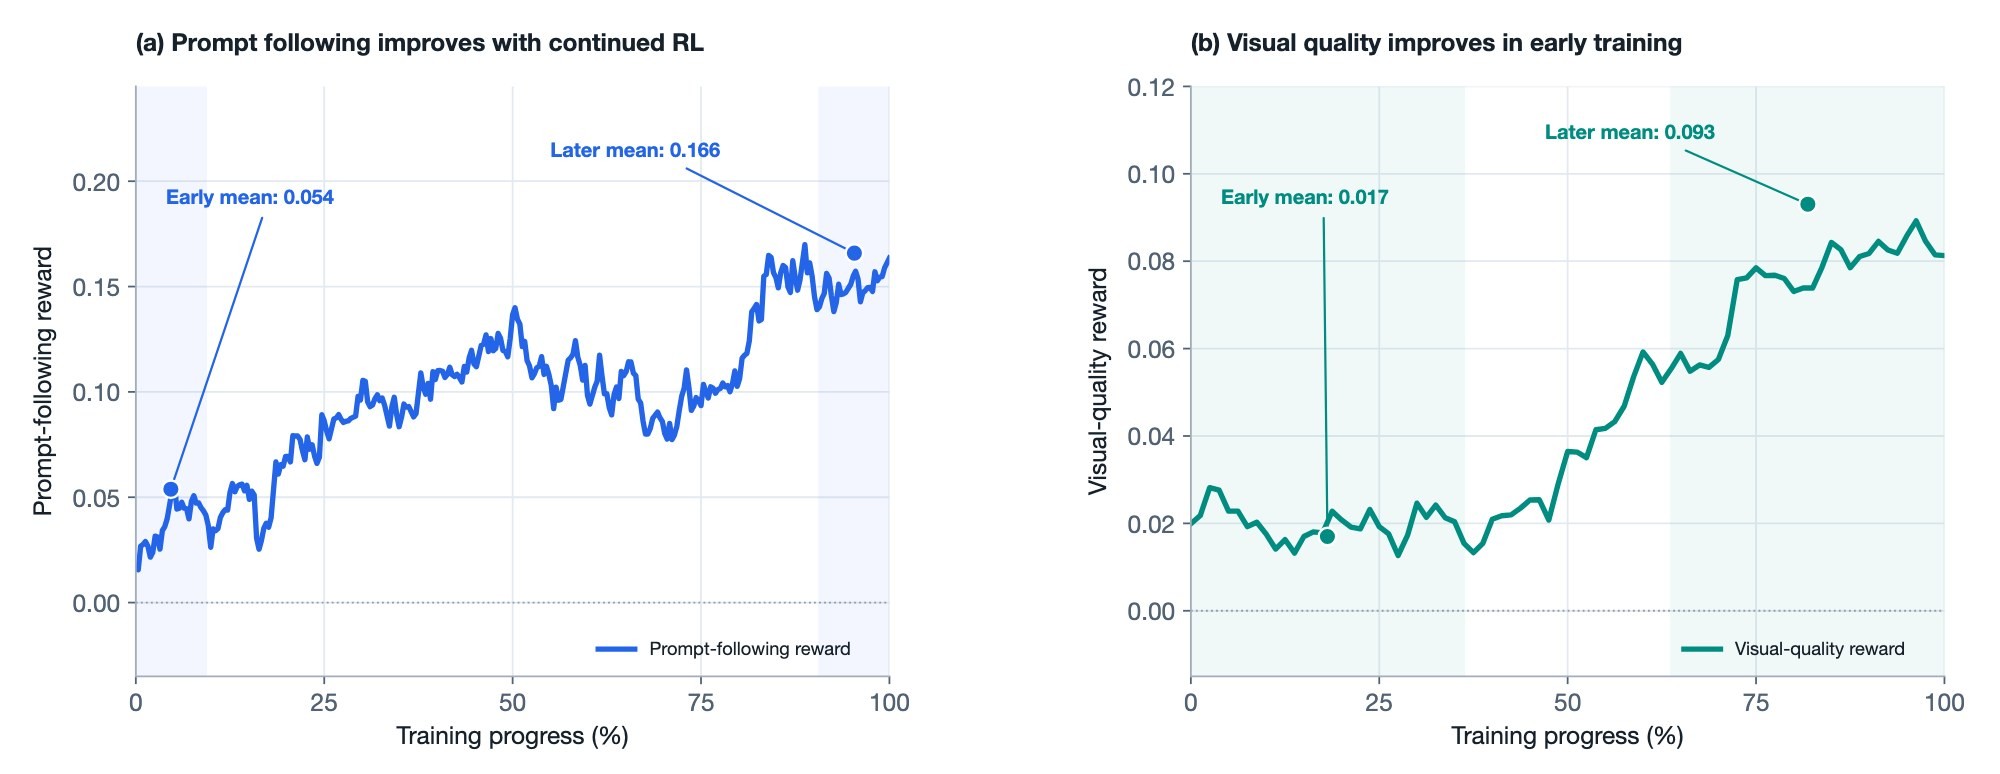
RL training raises prompt-following reward 0.054 → 0.166; early visual-quality reward improves 0.017 → 0.093. Figure 5 tracks the logged training objectives.
3.4 · How evaluation decides what to train next
Recurring failures set the next training priority. Product drift triggers targeted collection of packaging and handling footage, followed by curation, training and comparison with the incumbent. A candidate advances when product preservation improves without quality regression.
Figure 7 shows how candidate footage accumulates and quality gates determine what enters the next training dataset.

Qualitative evaluation
Matched briefs, original outputs. Boreal-H3 is on the left in every pair.
Product + anatomical consistency
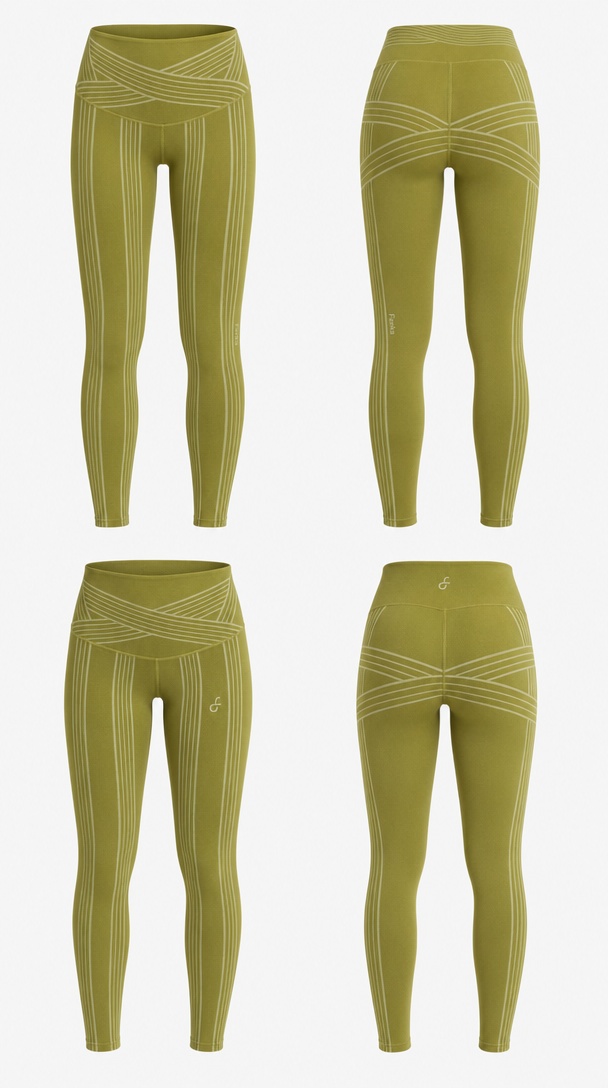
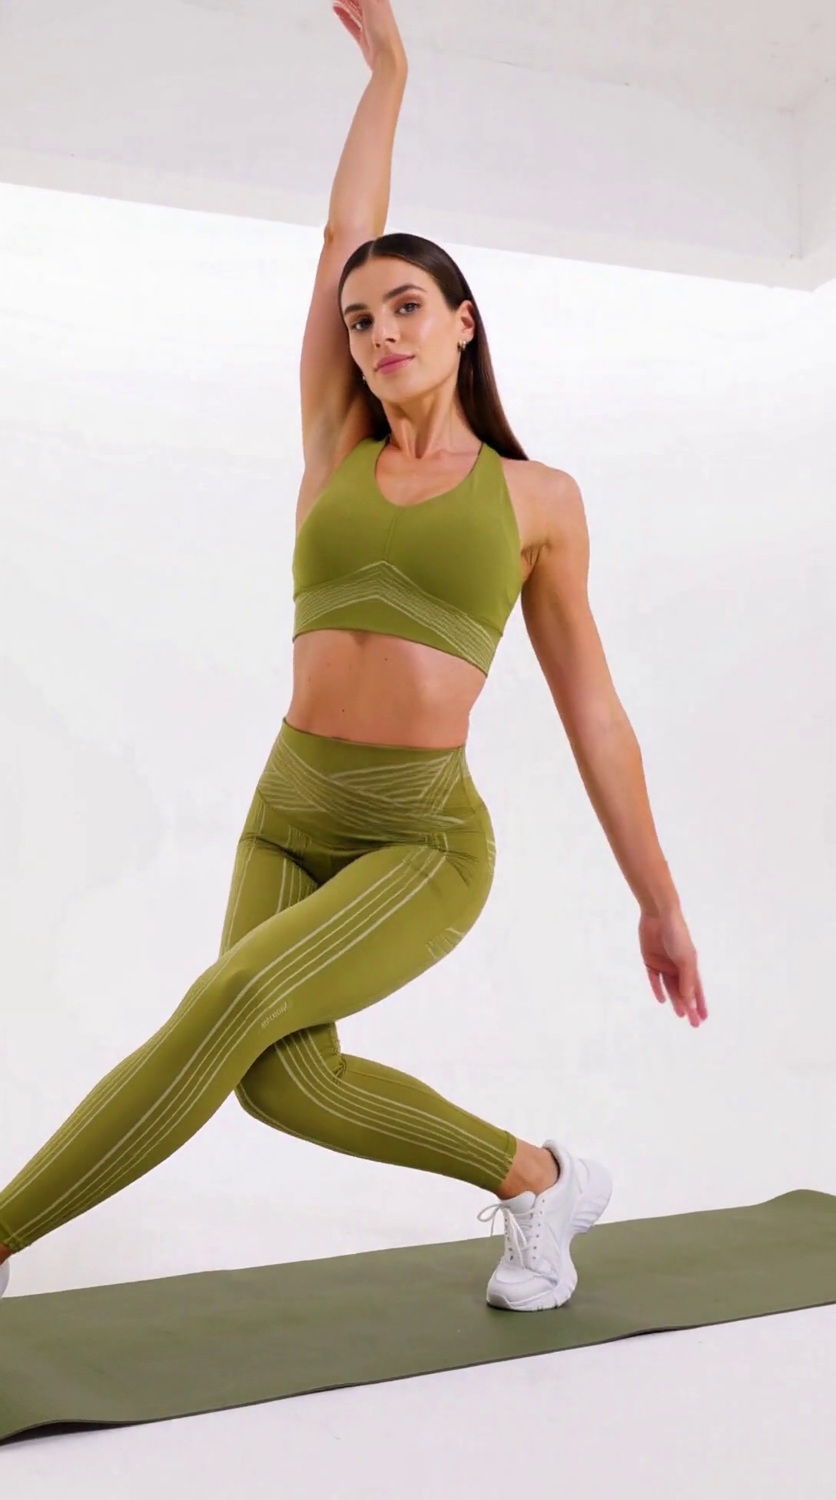
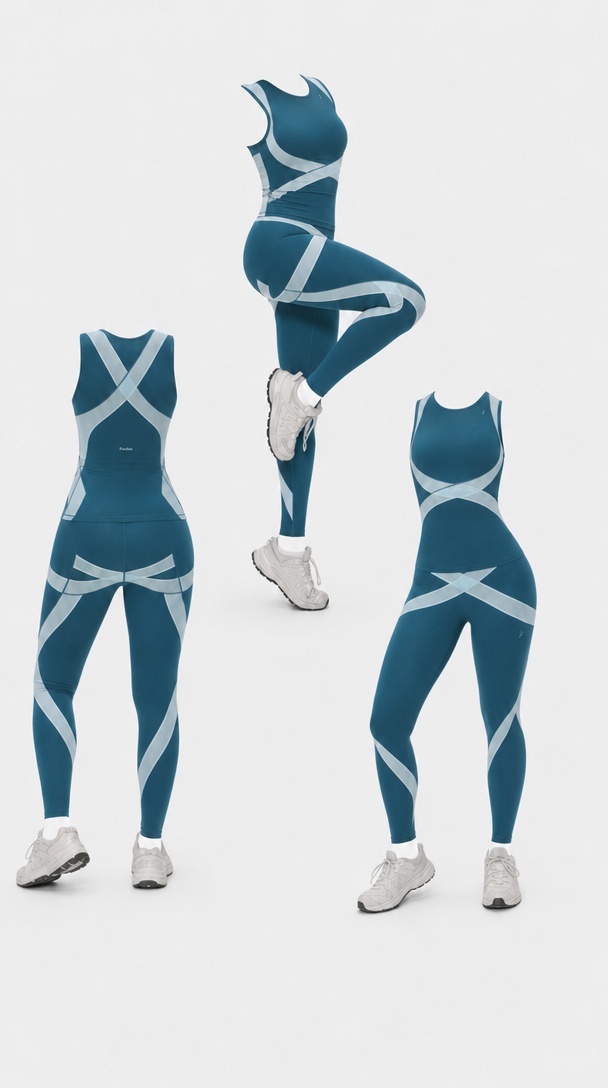
Cinematic commercial montage of leggings
Brief: Use the supplied leggings views, preserve the garment, and create a cinematic montage with dynamic camera movement.
Product detail
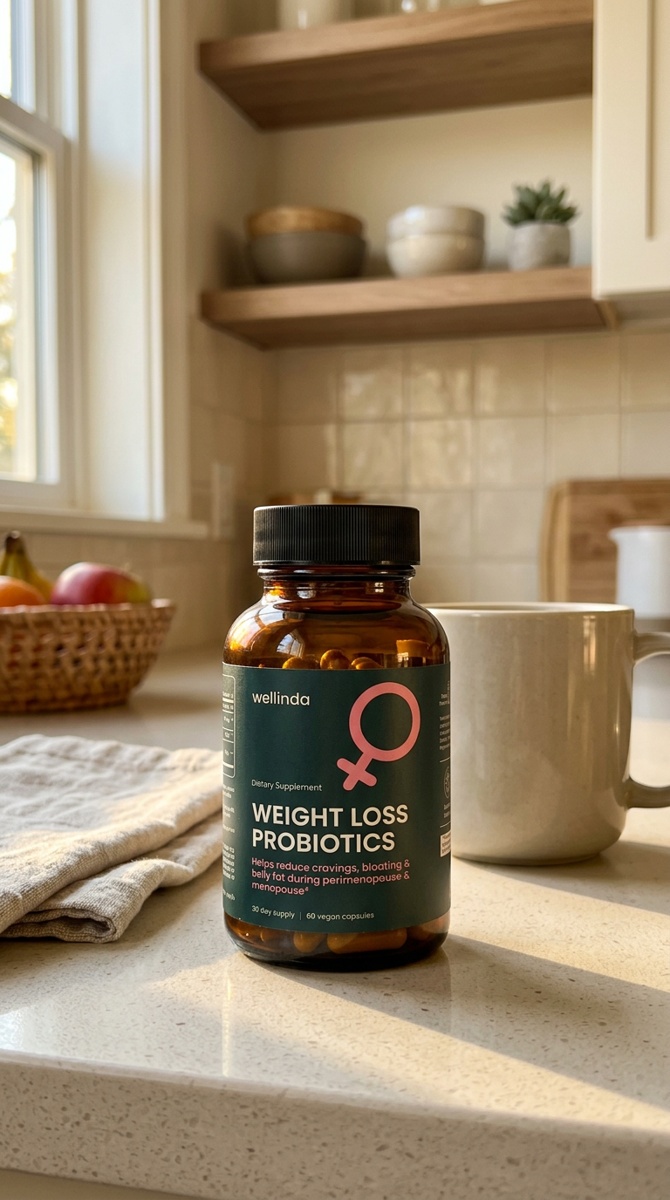
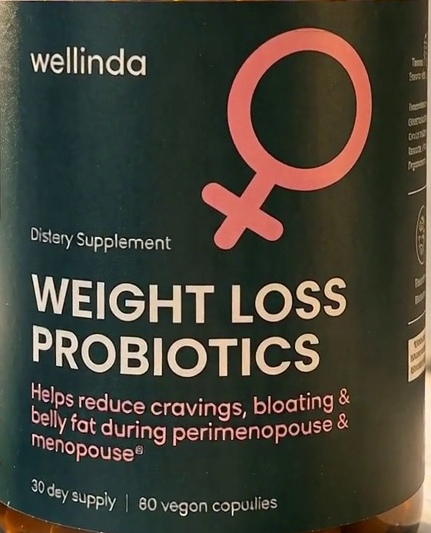
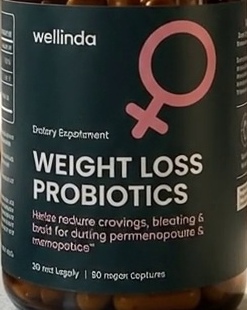
Probiotic bottle on a morning kitchen countertop
Brief: Keep the exact bottle design, typography, logo, cap and proportions unchanged in a naturally lit kitchen.
Long sequence execution
Wingsuit cliff jump to beach hot dog
Brief: Cliff launch → wingsuit flight past yachts → beach landing → vendor → hot-dog bite. The supplied prompt requests one continuous narrative.
Shot list + scene interpretation
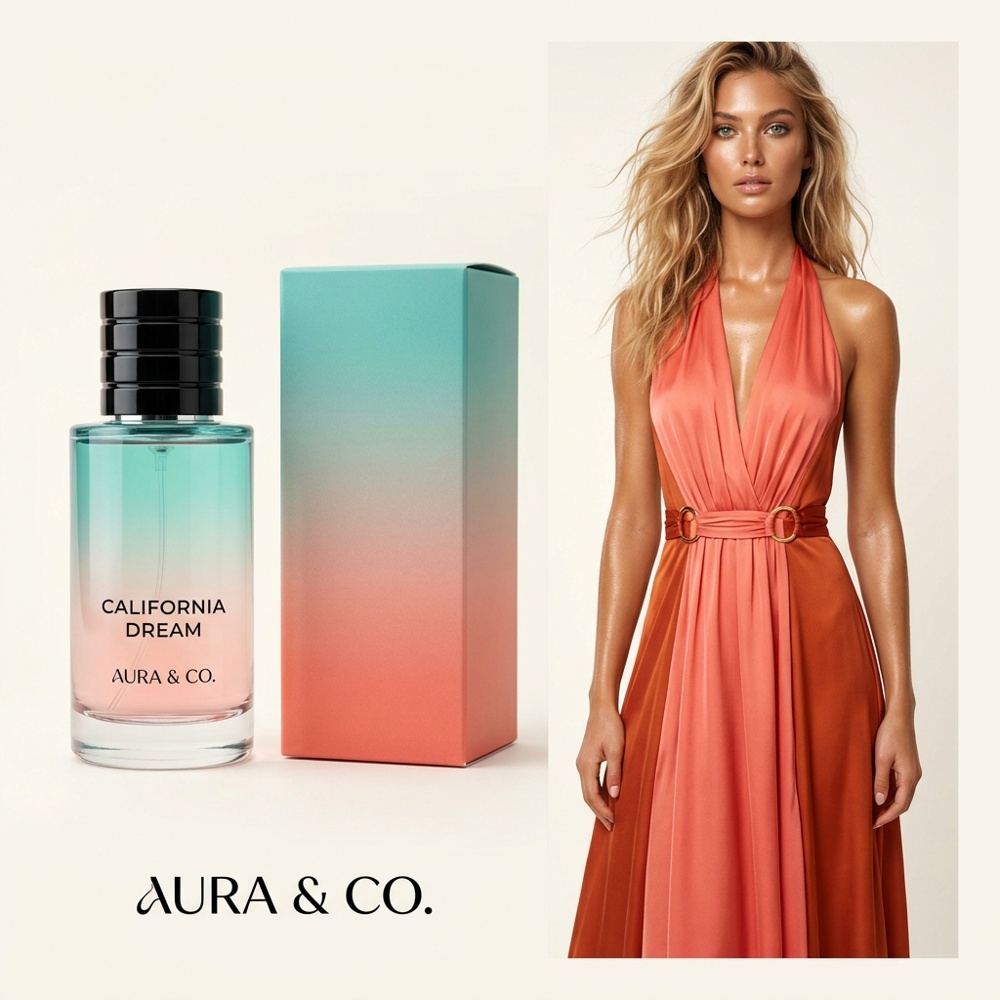
Perfume commercial on a sunlit pier
Brief: Follow the perfume shot list: pier cross-beams, the heroine, sensory close-ups and the gradient bottle hero shot.
Product geometry during handling
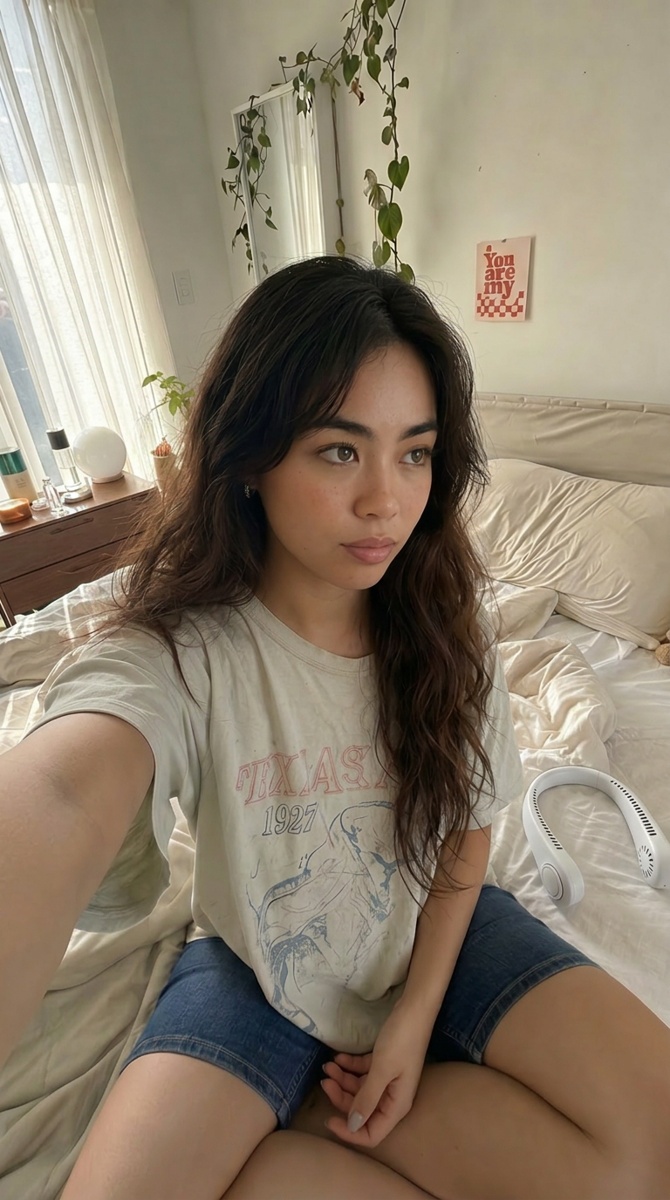
Woman holding up a portable neck fan
Brief: The creator picks up a white portable bladeless neck fan and holds it up during a selfie-style hook.
Character + diagram consistency
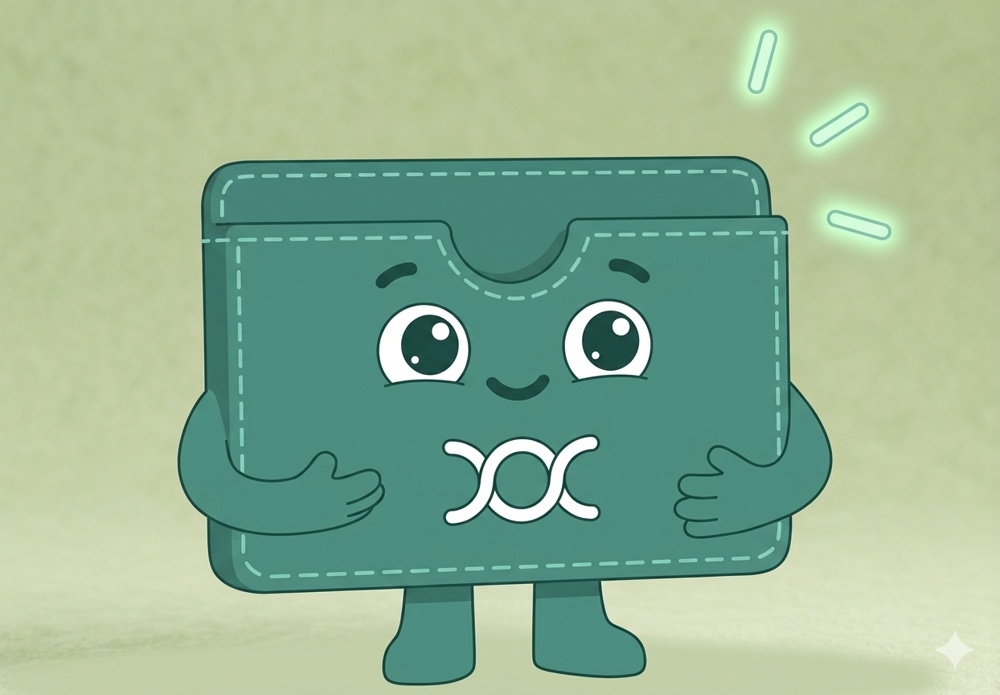
Animated green wallet deductible explainer
Brief: A cheerful green wallet on a light background: coins arrive, the deductible bar fills, then a second connected bar appears. No on-screen words.
Garment demonstration
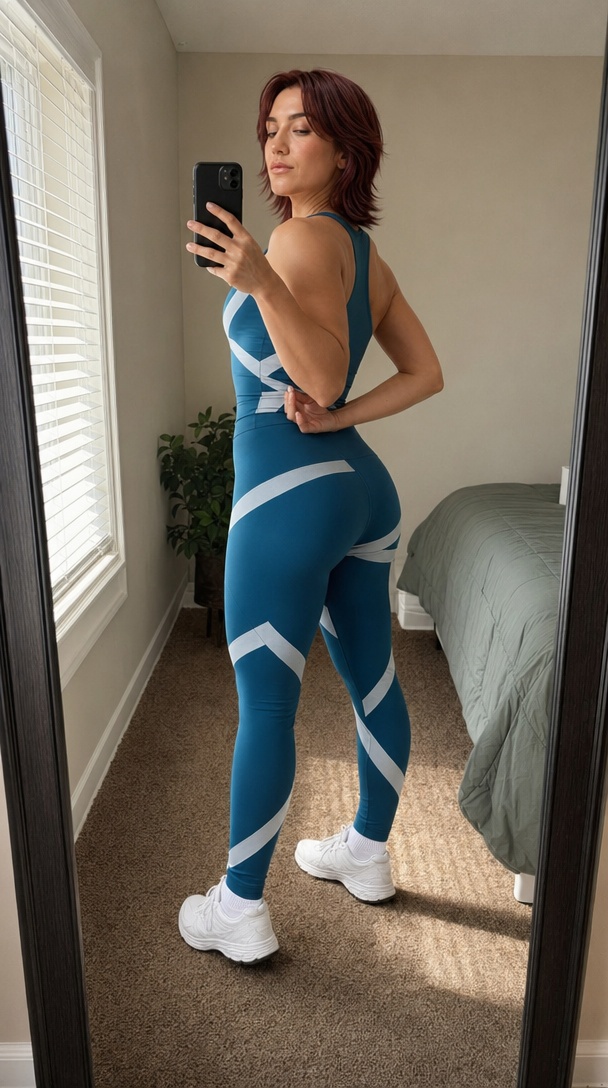
Woman presenting a tank top in a mirror
Brief: A natural phone-filmed mirror review: run a hand along the fabric, turn to show the racerback, and remove visible logos.
04 · Build with Boreal-H3
From a model to a better advertising workflow.
Direct model access is available in Model Playground. Start from text, control the opening and optional ending frames, or use Boreal-H3 Reference to combine the assets your shot needs.

With Boreal-H3, we are also revamping our Creative Agent into Creatify Ad Agent. The aim is to connect stronger video generation to the complete advertising workflow: develop an idea, produce variations, review the outputs, and turn more creative directions into experiments.
That is the opportunity: give an agent more room to explore hooks, demonstrations, and audience-specific variations. The model evaluations measure creative execution. Real campaign testing still has to determine which ads convert.
The next era of advertising should be limited by the strength of an idea—not the cost of producing it. Boreal-H3 is our next step toward that future: a model post-trained for product fidelity, creator identity, and brief execution at $0.04 per video-second; Creatify Ad Agent, which turns a brief into variations worth testing; and a feedback-driven loop that decides what to improve next and carries each lesson into the next model. We’re building more than a video generator: a system that learns what to improve next, so creative can scale like software.