Aurora
Aurora
Aurora
Our audio-driven avatar model. One photo and one audio clip become a lifelike talking video, in any language.
Our audio-driven avatar model. One photo and one audio clip become a lifelike talking video, in any language.
Our audio-driven avatar model. One photo and one audio clip become a lifelike talking video, in any language.

Available on
Available on




Most models animate a mouth.
Aurora animates a whole person.
Most models animate a mouth.
Aurora animates a whole person.
Same photo, same audio, side by side with a competitor.
Here's where Aurora pulls ahead.
Same photo, same audio, side by side with a competitor.
Here's where Aurora pulls ahead.
Object consistency
Aurora preserves the product's shape and branding as the hand moves. The competitor's object deforms over the clip and generates an incorrect logo on the subject's clothing.
IN PRODUCTION
IN PRODUCTION
Proven at scale.
Proven at scale.
videos generated per month
seconds of video (≈465 hrs)
render success rate
Studio quality,
Studio quality,
Studio quality,
without the studio price.
without the studio price.
/ second
Transparent, usage-based pricing. Pay by the second, not by the seat or an opaque credit bundle.
480p at $0.07/sec, 720p at $0.14/sec, live on fal with no contract.
Pricing shown for the fal API. Figures pending final confirmation before launch.
One model,
One model,
Marketing
Sales
Learning & development
Socials and creators
03/04
Learning & development
Onboarding, compliance, and training videos, updated in minutes and localized instantly.
03/04
Learning & development
Onboarding, compliance, and training videos, updated in minutes and localized instantly.
HOW AURORA WORKS
HOW AURORA WORKS
One model, three signals.
One model, three signals.
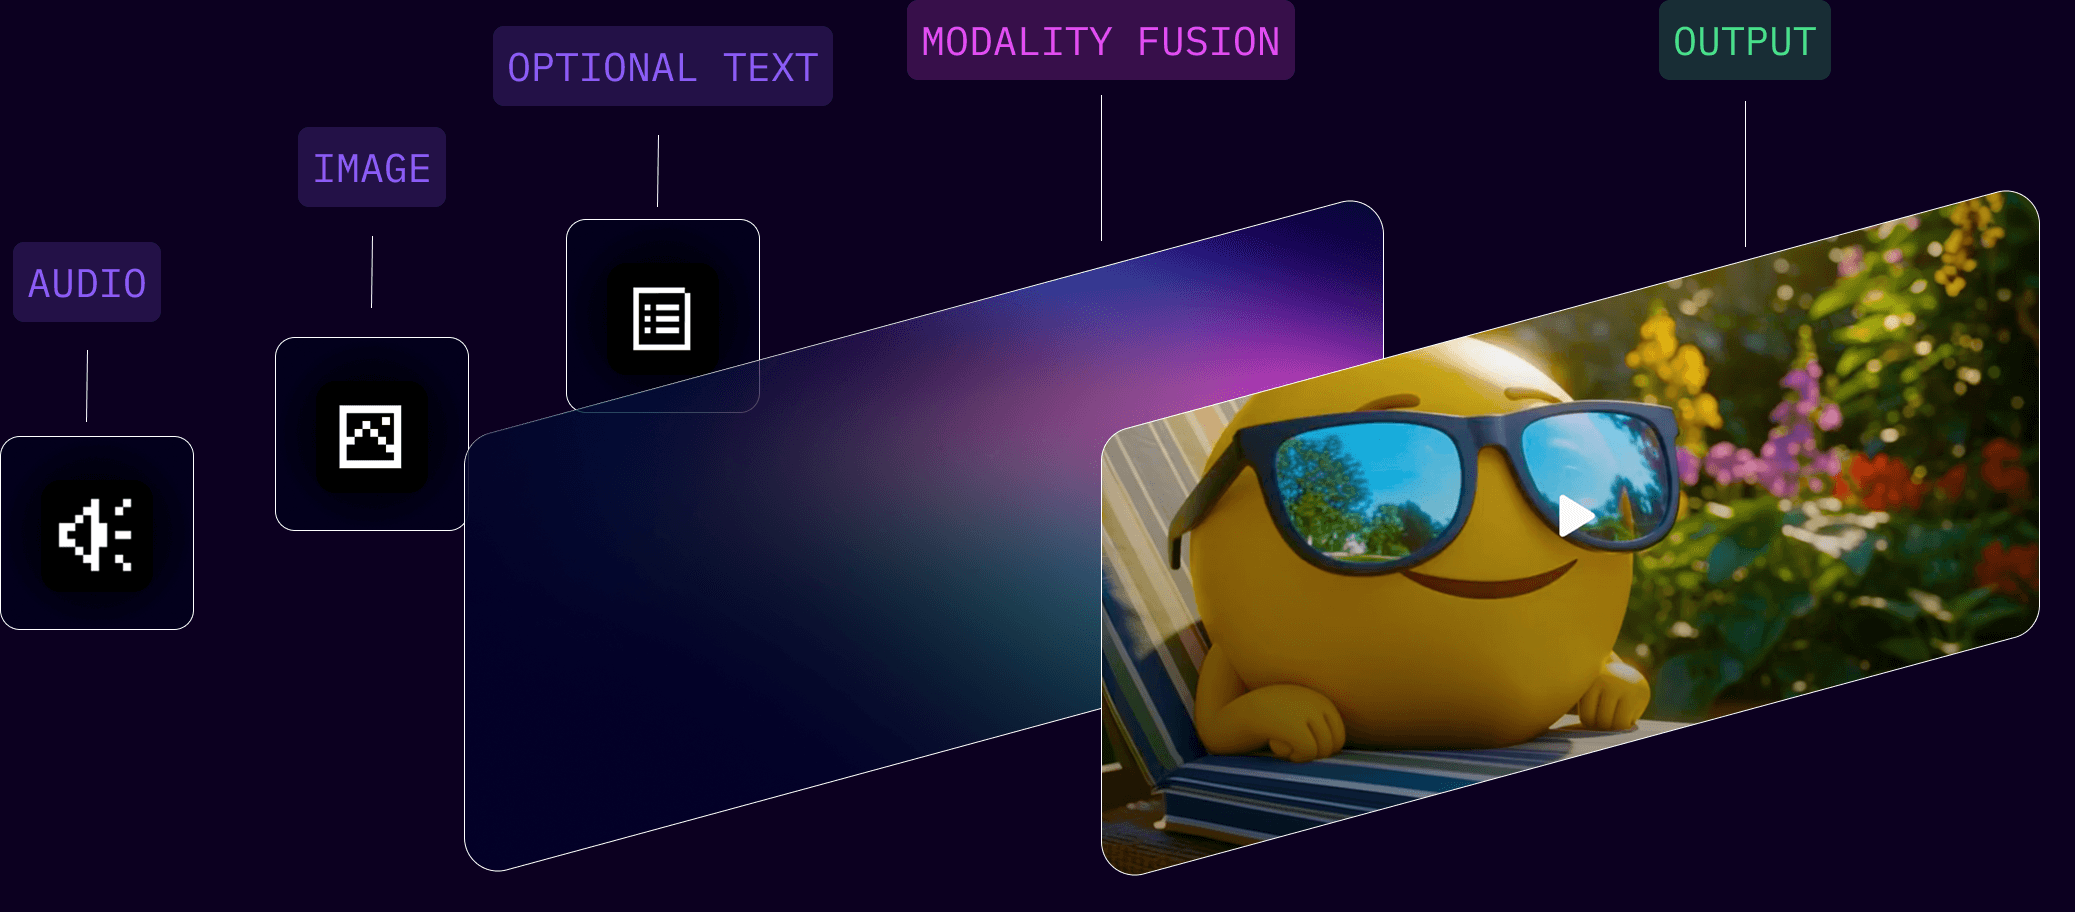
Aurora fuses an image, audio, and text encoder into a shared latent space.
It doesn't just move a mouth. It reads the emotion in the voice and renders the whole performance to match.
Zero-shot, from a single image, with no identity drift.
Aurora fuses an image, audio, and text encoder into a shared latent space.
It doesn't just move a mouth. It reads the emotion in the voice and renders the whole performance to match. Zero-shot, from a single image, with no identity drift.
IN PRODUCTION
IN PRODUCTION
How Aurora compares.
How Aurora compares.
We put Aurora side by side with leading avatar models across the details that make a video feel human, from breathing to eye contact. Aurora comes out ahead on nearly every one.
Aurora is Creatify Labs' AI avatar model for turning a single photo and an audio clip into a talking video. In head-to-head comparisons against tools like HeyGen, Hedra, and OmniHuman, it leads on lip-sync accuracy, facial expression, natural body movement, and holding fine detail steady over the length of a clip. It generates in any language from your own audio or text to speech, which makes it a strong fit for AI video ads, avatar-led product demos, sales outreach, and training content at scale.
We put Aurora side by side with leading avatar models across the details that make a video feel human, from breathing to eye contact. Aurora comes out ahead on nearly every one.
Aurora is Creatify Labs' AI avatar model for turning a single photo and an audio clip into a talking video. In head-to-head comparisons against tools like HeyGen, Hedra, and OmniHuman, it leads on lip-sync accuracy, facial expression, natural body movement, and holding fine detail steady over the length of a clip. It generates in any language from your own audio or text to speech, which makes it a strong fit for AI video ads, avatar-led product demos, sales outreach, and training content at scale.


The research lab building lifelike AI video models.


Creatify Lab • Copyright © 2026
The research lab building lifelike AI video models.
Creatify Lab • Copyright © 2026
The research lab building lifelike AI video models.
Creatify Lab • Copyright © 2026
The research lab building lifelike AI video models.
Creatify Lab • Copyright © 2026